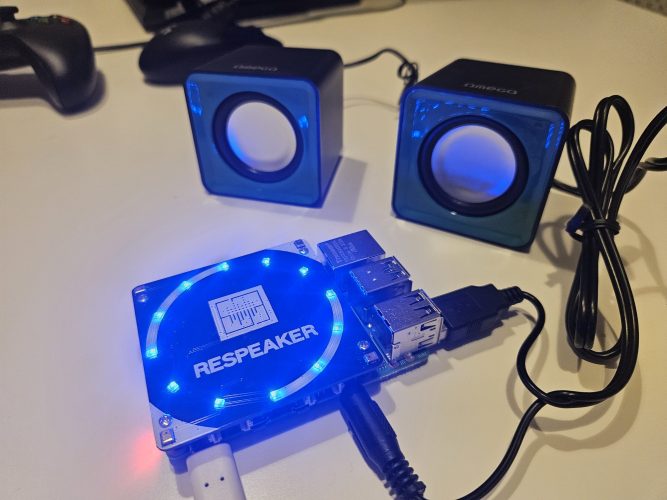
i’ve been playing for a while with the idea of having a real personal assistant at home. not alexa, not google, not something that phones home more than it listens to me. something i can break, fix, extend, and eventually turn into a platform for games with friends, silly experiments, and maybe a bit of madness.
this is how LLMRPiAssistant happened.
why another voice assistant?
mostly because i could. but also because the current generation of LLMs finally made this kind of project pleasant instead of painful. speech recognition that actually works, text-to-speech that doesn’t sound like a depressed modem, and conversational models that don’t need hand-crafted intent trees for every possible sentence.
i had a Raspberry Pi 4 lying around. i also had a reSpeaker 4-Mic HAT from SeeedStudio, which i always liked because:
- it has a proper microphone array,
- it does beamforming and noise handling reasonably well,
- and it comes with that ridiculously satisfying LED ring.
the rest was just software glue and some driver patching.
by the way, if you’re missing a Raspberry Pi or a reSpeaker, check the links.
what it does today
at the moment, LLMRPiAssistant is a fully working, always-on, wake-word-based voice assistant that runs locally on a Raspberry Pi and talks to OpenAI APIs for the heavy lifting.
the flow is simple and robust:
- it listens continuously for a wake word (using OpenWakeWord)
- once triggered, it records your voice
- it sends the audio to Whisper for transcription
- the text goes to a chat model (default: gpt-4o-mini)
- the response is turned into speech via TTS
- the Pi speaks back, with LED feedback the whole time
no cloud microphones, no mysterious binaries. just python, ALSA, and some carefully managed buffers.
things i cared about while building it
this project is very much shaped by past frustrations, so a few design decisions were non-negotiable:
- local-first audio wake word detection and recording happen entirely on the Pi. the cloud only sees audio after i explicitly talk to it.
- predictable state machine listening, recording, processing. no weird overlaps, no “why is it still listening?” moments.
- hardware is optional no LEDs? no problem. want to test it over SSH without speakers? it still works.
- configuration over magic everything is configurable: thresholds, models, voices, silence detection, devices. if something behaves oddly, you can tune it.
- logs, always logs every interaction is logged in JSON. if it fails, i want to know why, not guess.
the code
the repository is here: 👉 https://github.com/bdobrica/LLMRPiAssistant
the structure is boring in a good way: audio handling, OpenAI client, LED control, config, logging. nothing clever, nothing hidden. if you’ve ever debugged real-time audio, you’ll recognize the paranoia around queues and buffer overflows.
there’s also a Makefile that does the full setup on a clean Raspberry Pi, including drivers for the reSpeaker card. reboot, and you’re good to go.
what’s missing (and why that’s the fun part)
the assistant works. that box is checked. ✅ but i didn’t build it just to ask for the weather.
the real goal is voice-controlled games. sitting in a room with friends, no screens, just talking, arguing, laughing, and letting the assistant keep score, manage turns, and generate content.
that’s why the TODO list is… long. some highlights:
- conversation history that doesn’t grow until it explodes
- multi-player support with turn management
- local command parsing for low-latency actions (“roll dice”, “next turn”)
- persistent game state
- trivia, story games, word games, party games
- eventually, local models for fast responses
in other words: turning a voice assistant into a game master.
why open source
because this kind of project only gets interesting once other people start breaking it in ways i didn’t anticipate. different microphones, different accents, noisy rooms, weird use cases.
also, i’m long past the phase where i enjoy building things in isolation. if someone forks this and turns it into something completely different, even better.
what’s next
short term: fix the rough edges, especially around audio devices and conversation history.
medium term: multi-player games. actual playable stuff, not demos.
long term: hybrid local/remote intelligence, so latency stops being annoying and the assistant feels present instead of “waiting for the cloud”.
for now, i’m just happy that a small box on my desk lights up, listens, and talks back – and that i understand every single line of code that makes it happen.
more to come.